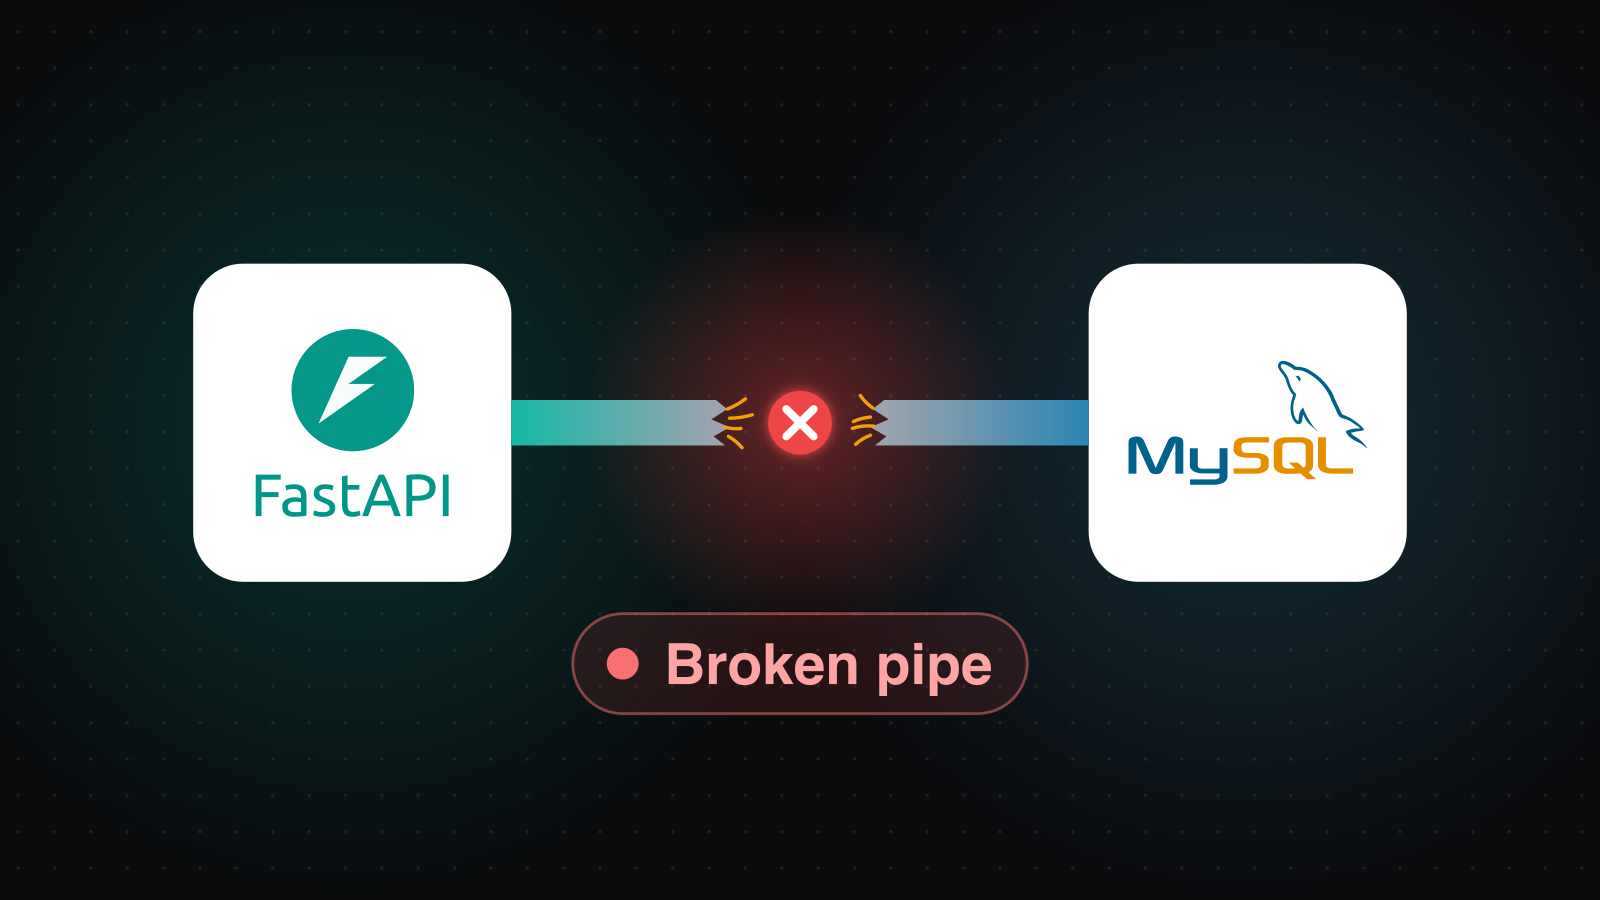
(2006, "MySQL server has gone away (BrokenPipeError(32, 'Broken pipe'))")This error showed up once or twice a month, usually before dawn or on the first request of the morning. A retry made it go away, and the next month it came back at the same time of day. It sat low on the priority list for a while. Then one Tuesday the rate jumped to ten times its usual level, and I decided to chase it down.
#The short answer, and when it applies
Put simply, my reading is this: a session that never gave its DB connection back when the request ended stayed on a thread, and the first query of the morning went out on that same connection, which the DB had dropped overnight. The option that checks connections only runs when a connection is borrowed from the pool, so it never looked at the one the session was already holding.
When you use scoped_session with default settings in FastAPI, sync endpoints run on worker threads, and the session gets bound to that thread instead of the request. If a request ends without commit() or close() and leaves the session holding its connection with a transaction open, then on a thread that sits idle long enough, MySQL’s wait_timeout (how long the server waits before dropping an idle connection, 8 hours by default) closes that connection, and the next request fails with Broken Pipe (2006) or Lost connection (2013).
The fix was to look sessions up per request instead of per thread, and to clean up that session at the end of every request. Concretely, I changed scopefunc, which decides the key used to find a session, to a function that returns the request ID from a ContextVar, and called remove() in a middleware on every request. The business code didn’t change. In the month after the deploy, the error didn’t come back.
If all of the following hold, you likely have the same problem.
- You use
scoped_sessionwithout ascopefunc. - Requests end without
commit()orclose(), so the session holds a connection with a transaction open. - Sync endpoints declared with
defrun on a worker thread pool. - Your DB drops idle connections through
wait_timeout, as MySQL and MariaDB do. - Traffic is uneven, so some threads sit idle for a long time. This still counts if a
defhealth check that never touches the DB keeps coming in.
If going through the conditions one by one is hard, log the pool status at a time when no request is in flight. If there are no requests and no background jobs, yet the number of connections borrowed from the pool and never returned (checked-out connections) isn’t zero, that’s a sign something is skipping the return. With several worker processes, each process has its own pool, so check each one. On SQLAlchemy 2.1.5, leaving two sessions that ended without a commit on their threads printed this:
print(engine.pool.status())
# Pool size: 5  Connections in pool: 0 Current Overflow: -3 Current Checked out connections: 2
These numbers alone don’t tell you who’s holding the connections. If you suspect something, turn on checkout and return logging with create_engine(..., echo_pool="debug") and look for connections that never log a return after their request ends.
The fix cleans up the session when the middleware sends the response. If the same session is also used in streaming responses or background jobs, read the constraint under things to watch first. If you run DB work in parallel within a single request, those tasks need their own sessions.
#Symptoms and what I suspected first
The pattern was clear.
- It happened when requests came back after a stretch with no traffic.
- It lined up with MySQL’s default
wait_timeoutof 8 hours. - It didn’t cluster on one endpoint. It was spread across many APIs.
- It didn’t go away even though
pool_pre_ping=Truewas already on.
The last one was the strangest. An application doesn’t open a new DB connection every time. It keeps connections in a pool and borrows them, and the moment it takes one out of the pool is called a checkout. pool_pre_ping pings the connection at checkout to see if it’s alive and swaps in a new one if it’s dead. The SQLAlchemy docs present it as the way to guard against dropped connections, and we’d had it on as a production default for a long time.
I suspected MySQL first. wait_timeout is how long the server waits on a connection that sends no queries before dropping it, and the default is 28800 seconds, or 8 hours. I didn’t think our traffic often went quiet for 8 hours. At the time I was counting gaps per endpoint, and an endpoint whose first request of the day arrived between 4 and 8 a.m. had gone 8 hours without a request. I raised wait_timeout to 16 hours. The next week, the same thing happened again.
I didn’t confirm at the time why it came back after the increase. Looking back, there are two possible explanations. When a non-interactive connection, like one from an app, is established, MySQL copies the global wait_timeout into that connection’s own setting. If you change only the global value, connections that were already open keep using 8 hours, and as we’ll see below, our sessions kept holding those old connections. A weekend can also stretch a gap past 16 hours. Even for connections that did pick up the new value, a longer timeout only pushed back the moment they got dropped.
I added pool_recycle=3600 too. At checkout, it swaps out any connection created more than an hour ago. The improvement was marginal. Only then did I notice that both options do their work only at checkout. If some connection gets reused without a checkout, neither option can touch it. That was the first clue pointing to the cause.
Later I confirmed that pool_pre_ping itself wasn’t broken. It worked fine on connections that went through a checkout. The errors came from cases where the session reused a connection it was already holding, with no new checkout. I never did figure out why the rate jumped tenfold that Tuesday.
#The cause: the session is bound to the thread, not the request
Three terms first. A connection is the actual open link between the app and the DB. A transaction is a group of DB operations that are committed or rolled back together, and in this setup even a read starts one. A SQLAlchemy session is the object that manages ORM objects and transactions. Bound to a single engine, as in this post, a session checks a connection out of the pool on its first DB access and holds it, and it gives the connection back only when the transaction ends with a commit or rollback, or when the session is closed. That’s why even a read-only GET request can send its response and still finish holding a connection.
Two more words that come up often. A thread is a unit inside a program that runs one piece of work at a time, and middleware is code that runs before and after every request.
#The default scope of scoped_session is the thread
scoped_session lets you call session_factory() from anywhere and get the session for the current scope, without passing the session around. With the default settings, that scope is the thread. Think of it as giving every thread its own locker: the first call creates a session and puts it in the locker, and every call after that hands back the same session from the same locker. Internally, a ThreadLocalRegistry built on threading.local() plays the role of that locker.
This default fits WSGI setups well. WSGI is the interface that traditional Python web frameworks like Flask, Django, and Pyramid use to talk to the web server. In a traditional sync setup, one request is handled from start to finish inside a single worker thread, so you clean up the session on that thread when the request ends. Flask-SQLAlchemy also calls remove() at the end of a request, though since 3.x it uses the app context as the scope instead of the thread. The SQLAlchemy docs spell out this assumption too.
“most Python web frameworks, with notable exceptions such as the asynchronous frameworks Twisted and Tornado, use threads in a simple way, such that a particular web request is received, processed, and completed within the scope of a single worker thread.”
Source: SQLAlchemy docs, Using thread-local scope with web applications
If a thread is a request, binding the session to the thread binds it to the request. Under WSGI, calling remove() at the end of each request was enough with the default settings.
#Under ASGI, one request passes through several threads
FastAPI and Starlette run on ASGI. ASGI is the interface between an async web server and the app. A single front desk called the event loop serves many requests in turn and hands slow sync work to worker threads in the back. Middleware and async def endpoints run on the event loop thread, while sync endpoints and sync dependencies declared with def go to a worker thread pool managed by anyio. The two ends of a request live on the event loop thread, but the sync endpoint that creates the session lives on a worker thread. There’s also no guarantee that a sync dependency and a sync endpoint land on the same worker thread.
The worker reuse and cleanup described below is what I confirmed in the 4.15.1 source of anyio’s asyncio backend, which FastAPI uses by default. Worker threads come from a pool whose concurrency anyio’s CapacityLimiter caps at 40 by default, and the same thread takes many requests in turn. When a new call arrives, anyio reuses the worker that most recently went idle, and at that point it cleans up the other workers that have been idle for 10 seconds or more. A threading.local() store is garbage collected only when its thread ends, so as long as the worker is alive, that thread’s session stays too.
If no calls come in overnight, nothing triggers that cleanup, so the first request of the morning goes to the worker that last did any work. The same thing can happen even when the process isn’t completely idle. If a def health check that never touches the DB keeps reusing that worker, the worker stays alive while the connection held by its session sits idle.
I couldn’t confirm which worker sat idle for how long during the incident, because there were no logs for it. This path is a reconstruction from reading the anyio implementation.
If the cleanup is missing, every worker thread that used a session can end up with one session left over. This structure is probably also why the error didn’t happen every day. A dropped connection gets reused only when the last request on the worker that takes the first request after a gap ended with its transaction still open. If that request ended with a commit, the connection had already gone back to the pool, so the next DB access went through a checkout, and at that point pool_recycle or pool_pre_ping filtered out the stale connection.
So what gets dropped is the connection held by the worker thread’s session, and the 8-hour clock starts not at the endpoint’s last request but at the last time that connection was used.
The same structure can leave one more symptom besides connection errors. If the worker’s next request keeps running inside the transaction the previous request opened, a plain SELECT under REPEATABLE READ, InnoDB’s default isolation level, keeps reading from the snapshot taken at its first read and can miss changes committed in the meantime. If you occasionally read stale data, the same cause is worth suspecting.
#The path to Broken Pipe
Our code didn’t call close() at the end of a request. The session stayed on the worker thread, holding its connection with a transaction open.
Because the session holds the connection directly, no checkout happens on the pool. pool_pre_ping, which works only at checkout, gets no chance to step in.
The two codes at the end of the diagram share one cause in this flow, and which one you get depends on the state of the dropped socket. When I reproduced it with FastAPI, MySQL 8.4, and PyMySQL, a query sent shortly after the server closed the connection got through the write and then failed at the read with 2013 Lost connection to MySQL server during query.
The 2006 BrokenPipeError we saw can be explained by a path that goes through TCP keepalive. Keepalive is a liveness probe the operating system sends on a connection that has been quiet for a long time, and PyMySQL turns it on. If the client is still holding a connection the server has already closed, the server side can answer that probe with a connection reset that says, in effect, “no such connection.” A query written after that fails on the write itself, and you get 2006. On Linux, with an 80-second gap between requests, a keepalive idle time at the default of 7200 seconds gave 2013, and cutting it to 5 seconds gave exactly 2006.
The Linux default idle time is another 2 hours from the last packet the server sent when it closed, so if the connection closed at 6:00 and the first request came at 9:00, as in the diagram, it fits this path. I didn’t check the actual idle time or keepalive settings in production.
I didn’t check why a retry made it go away. After a connection error, SQLAlchemy invalidates that connection, and to touch the DB again with the same session you first have to clear the previous transaction with rollback() or close(). If the retry went to the same session, that cleanup must have happened somewhere in the exception handling. It may also have gone to another worker’s session. Touching the DB again with the same session without that cleanup raises PendingRollbackError, so that’s worth searching your logs for as well.
#remove() in middleware never reaches the worker thread
It looks like cleaning up the session in middleware at the end of the request should do it. Code like this:
class CleanupMiddleware(BaseHTTPMiddleware):
    async def dispatch(self, request, call_next):
        try:
            return await call_next(request)
        finally:
            database.session_factory.remove()  # only touches the event loop thread's session
This code can’t remove the worker thread’s session. The default registry is per thread, so remove() only sees the session of the thread that called it. The middleware runs on the event loop thread and the session lives on a worker thread, so remove() returns without removing anything. For the same reason, close() called from middleware doesn’t reach the worker thread’s session either. While revising this post I checked again with SQLAlchemy 2.1.5 and a pool with one worker thread. In this reproduction the main thread stands in for the event loop thread, and it only looks at how the per-thread registry behaves.
default registry: ThreadLocalRegistry
after remove() from main thread, worker still has session: True
after remove() from worker thread, worker gets new session: True
I also reproduced the full request path separately with FastAPI and MySQL 8.4. Even with remove() called in middleware, checked-out connections stayed at 1, and the next request failed with the same 2013 as the earlier reproduction.
remove() only works when called on the worker thread that created the session. anyio decides which worker takes a request, and the request side has no say in it.
#close() and remove() do different jobs
“The
scoped_session.remove()method first callsSession.close()on the current Session, which has the effect of releasing any connection/transactional resources owned by the Session first, then discarding the Session itself.”
close()clears ORM objects and transaction state and returns the connection to the pool. The session object stays in the registry, and the next call returns the same object.remove()runsclose()and then deletes the session from the registry. The next call creates a new session.
Had we called close() every time inside the endpoint or Repository, that is, on the worker thread that created the session, the connection would have gone back to the pool and the next request would have gone through a checkout. Then pool_recycle and pool_pre_ping could have done their work, and the path where a connection held across requests gets reused without a check would have been closed. scoped_session gives you the session for the current scope without passing it as an argument, but cleaning up at the end of the request is on you. Our code skipped that cleanup.
#The fix: switching scopefunc to a ContextVar
#The idea
Pass your own scopefunc to scoped_session and it uses a ScopedRegistry instead of the ThreadLocalRegistry. This registry is a lookup table that pairs keys with sessions, which is to say a plain dictionary.
# SQLAlchemy ScopedRegistry internals (simplified)
class ScopedRegistry:
    def __init__(self, createfunc, scopefunc):
        self.createfunc = createfunc
        self.scopefunc = scopefunc
        self.registry = {}

    def __call__(self):
        key = self.scopefunc()  # everything depends on what this key is
        if key not in self.registry:
            self.registry[key] = self.createfunc()
        return self.registry[key]
If the key is a value unique to each request, each request gets its own session even when they run on the same thread. It’s like issuing a ticket number to every request and finding the session by that number.
The request ID goes into a ContextVar. A ContextVar is a context variable from the Python standard library that holds a separate value for each flow of execution, and here it plays the part of the ticket attached to each request. The ticket the middleware attaches follows the request all the way to the worker thread.
#Three files, one key line
I added one new module and one new middleware, and one scopefunc line to the existing Database class.
#ContextVar module (new)
# context_session.py
from contextvars import ContextVar, Token

_session_context: ContextVar[str] = ContextVar("session_context")

def set_session_context(context_id: str) -> Token:
    return _session_context.set(context_id)

def get_session_context() -> str:
    return _session_context.get()

def reset_session_context(token: Token) -> None:
_session_context.reset(token)#Database class (one-line change)
class Database:
    def __init__(self, engine: Engine) -> None:
        self.session_factory = orm.scoped_session(
            orm.sessionmaker(autocommit=False, autoflush=False, bind=engine),
            scopefunc=get_session_context  # ← this one line is the key
)#Middleware (new)
from starlette.middleware.base import BaseHTTPMiddleware
from starlette.requests import Request
from uuid import uuid4

class ContextSessionMiddleware(BaseHTTPMiddleware):
    async def dispatch(self, request: Request, call_next):
        context_id = str(uuid4())
        token = set_session_context(context_id)
        try:
            response = await call_next(request)
            return response
        finally:
            # The order remove() → reset matters:
            # remove() calls scopefunc() internally to find the current context's session.
            # If reset runs first, scopefunc() raises LookupError or returns a different value,
            # and this request's session never gets cleaned up.
            database.session_factory.remove()  # find and remove the current context's session
            reset_session_context(token)        # then reset the context

app.add_middleware(ContextSessionMiddleware)
That’s the code we put into production. If I were writing it fresh today, I’d add one more finally layer so the context is restored even if remove() raises.
        finally:
            try:
                database.session_factory.remove()
            finally:
reset_session_context(token)#Why the error goes away
It has the same shape as the earlier CleanupMiddleware, but this time remove() works. The key for finding the session is now the request ID, so even when it’s called from the event loop thread, it finds this request’s session.
remove() calls close() first, so the connection goes back to the pool at the end of every request. The next request starts with a new session and goes through a checkout on its first DB access. At that moment, pool_recycle=3600 swaps out any connection created more than an hour ago, and pool_pre_ping checks whether a reused connection has been dropped. What this fix really did was give those two options back their chance to work.
In the same reproduction setup, I set wait_timeout to 5 seconds, left an 8-second gap between requests, and compared before and after the fix. With the original code, and with code that only called remove() in middleware, one checked-out connection remained after the request ended, and the next read failed with 2013. With the scopefunc change, checked-out connections went back to 0 at the end of every request, and the read after the same gap succeeded because pool_pre_ping swapped the dropped connection for a new one. Leaving the concurrency limit at the default of 40 gave the same result.
This approach rests on one assumption. Starlette’s run_in_threadpool calls anyio’s to_thread.run_sync, and anyio copies the context at call time and runs the function in it on the worker thread. In effect, the ticket attached to the request is handed over along with the work, so the request ID the middleware set reaches session_factory() inside the endpoint with the same value.
From the day after the deploy, MySQL server has gone away stopped showing up, and it hasn’t appeared once in the month since. But this was an error that used to show up once or twice a month, so a month isn’t long enough to call it settled, and I’m still watching. I didn’t run a separate load test, and the production dashboards showed no difference in memory usage or P99 response time before and after the deploy.
#Why I didn’t switch to the dependency injection pattern
The approach the FastAPI docs recommend is a yield dependency that opens and closes a session per request. Below is the Depends(get_db) example from the old SQL tutorial. The current docs do the same thing with a SQLModel session.
def get_db():
    db = SessionLocal()
    try:
        yield db
    finally:
        db.close()

@app.get("/users")
def get_users(db: Session = Depends(get_db)):
    return db.query(User).all()
The session lifecycle is visible in the code, and each request gets its own session. But if the codebase injects scoped_session globally through a dependency injection container, switching is expensive. You’d have to change how every UseCase and Repository receives its session, and fix the test code too. You could also add close() everywhere a session is used, but in a structure where sessions get pulled out all over the place, missing a single spot brings the same problem back.
This approach has had reported problems too. In FastAPI Discussion #6628, the thread pool filled up with requests waiting on connections, the dependency’s finally block couldn’t get a thread to run on, and the whole app froze. A maintainer replied that a fix in 0.82.0, released in September 2022, had probably resolved it.
Swapping scopefunc keeps the existing structure and fixes only the part that causes trouble. The SQLAlchemy docs recommend using the web framework’s integration tools instead of scoped_session where possible, and add that even otherwise, it’s better to associate the session directly with the request than with the current thread. This fix is a compromise that follows the second recommendation.
#Where other implementations bind the session
Looking around, other implementations use the same approach. The difference is the unit they bind the session to.
| Implementation | How the scope is determined | Bound to |
|---|---|---|
scoped_session default | threading.local() | Thread |
| Flask-SQLAlchemy | Flask app context | App context |
async_scoped_session docs example | current_task() | Async task |
| Galaxy Project | ContextVar, falling back to threading.get_ident | Request |
| This post’s fix | ContextVar.get() | Request |
Galaxy Project, a large bioinformatics platform, uses the same pattern on top of FastAPI. When there’s no request ID, it falls back to the thread ID.
#Things to watch when applying this
#1. Skipping remove() leaks memory
With the per-thread registry, there were only as many sessions as worker threads. With the request ID as the key, there can be as many as there are requests, so if remove() is skipped, the ScopedRegistry dictionary grows without bound. You have to call it in the middleware’s finally.
#2. Set and clean up the request ID in one place, the middleware
The BaseHTTPMiddleware in this example runs the downstream app in a separate task, and anyio copies the context when work moves to a sync dependency. So a value set in the middleware flows down to the dependencies, but a value set or changed in a dependency doesn’t flow back up to the middleware.
dependency-injector Discussion #493 also has a case where the middleware and a dependency couldn’t share the same session, and the author guessed the split context was to blame.
FastAPI Discussion #8017 has code that sets the request ID in middleware and cleans up the session in a dependency. A later reply pointed out that the middleware resets the context variable first, so remove() called in the dependency can’t find this request’s session, and the pool eventually runs dry. That report is from its time and doesn’t carry over directly to today’s setup. Python tasks and anyio workers take a copy of the context, so even if the parent resets later, the copied request ID stays the same. We put the ContextVar setup and remove() together in the middleware so the order of setting and clearing can be managed at a glance.
#3. BaseHTTPMiddleware cleans up once the response headers go out
call_next() returns once the response headers go out, so the example’s finally can run before a streaming body or background job finishes. If you use the same session while building the body or doing follow-up work, you need to design the cleanup timing separately. Cleanup code in a yield dependency can also run after the response, so check whether it uses the session.
remove() is a sync call, so if the session was holding a connection, it blocks the event loop until the rollback it sends on return finishes. If you need streaming responses in production, consider moving to pure ASGI middleware and cleaning up after the response body finishes.
#4. Keep pool_pre_ping and pool_recycle
Neither one could stop this problem on its own, but after the fix every request goes through a checkout, so they take back the job of filtering out dropped connections inside the pool. Remove them and the pool can hand out a dropped connection as is, and the first DB operation can fail with a connection error. Both are checks at checkout time, so they can’t protect against a connection that drops in the middle of a transaction.
#5. Handle code that uses sessions outside a request separately
The ContextVar in the example has no default. Calling session_factory() from an app startup hook, a batch job, a CLI, or a test that doesn’t go through the middleware raises LookupError. On those paths, set an ID yourself with set_session_context() and call remove() and reset_session_context() at the end, or make it fall back to the thread ID as Galaxy does. The fallback path is per thread again, so you have to clean up on that path yourself.
#6. Don’t use one session concurrently within a request
With thread scope, each worker thread had its own session, but with the request ID as the key, all code within one request gets the same session. If one request sends several DB operations to worker threads at the same time, two threads end up sharing one session. When I reproduced this with anyio, two worker threads got the same session object. SQLAlchemy sessions aren’t safe for concurrent use, so open a separate session for that kind of work.
#Before and after
| Item | Before: default scope, missing cleanup | scopefunc and ContextVar |
|---|---|---|
| Session isolation unit | Thread | Request |
remove() at request end | Works only on the thread that created it | Works from the event loop thread too |
| Checkout on the next request | Skipped, reuses the session’s connection | Checkout on first DB access, pool options run |
Broken Pipe risk | Yes, through idle threads | Idle-thread path removed |
| Concurrent DB work in one request | A different session per thread | Shares one session, open separate ones |
| Code added | None | 1 module, 1 middleware, 1 line changed |
Changes to UseCase and Repository | Not needed | Not needed |
The direct cause was not cleaning up the session when the request ended. Adding remove() to middleware couldn’t fix it on its own because we’d carried the WSGI-era assumption of “one thread, one request” straight into an ASGI environment. The key change was one line, but finding where that line belonged took several days.
If you use scoped_session in FastAPI and occasionally see errno 32 or 2013 errors in the early morning, check what your session is bound to before adding pool_pre_ping. If you didn’t pass a scopefunc, the answer is the thread.
#References
- SQLAlchemy 2.0 docs, Contextual sessions: covers the design assumption behind
scoped_session, the difference betweenclose()andremove(), and customscopefunc. - MySQL docs,
wait_timeout: explains that the session value is initialized from the global value when a connection is established. - fastapi/fastapi Discussion #8017: compares
scoped_session, dependency injection, and middleware approaches, and shares a case solved withContextVarandscopefunc. - fastapi/fastapi Discussion #6628: a report of a deadlock caused by a blocked thread pool with dependency-injected sessions.
- sqlalchemy/sqlalchemy Discussion #8891: has a comment from zzzeek that concurrency issues involving FastAPI have been increasing.
- ets-labs/python-dependency-injector Discussion #493: a case where FastAPI middleware and dependencies couldn’t share the same session.