LLM tokens are moving from code to knowledge. On April 3, 2026, Andrej Karpathy posted on X, and within days the post was near the top of Hacker News. He wrote that he was building personal knowledge bases on topics he cared about with an LLM, and put it this way.
“A large fraction of my recent token throughput is going less into manipulating code, and more into manipulating knowledge.”
Source: Andrej Karpathy, X
#Three directories and three operations
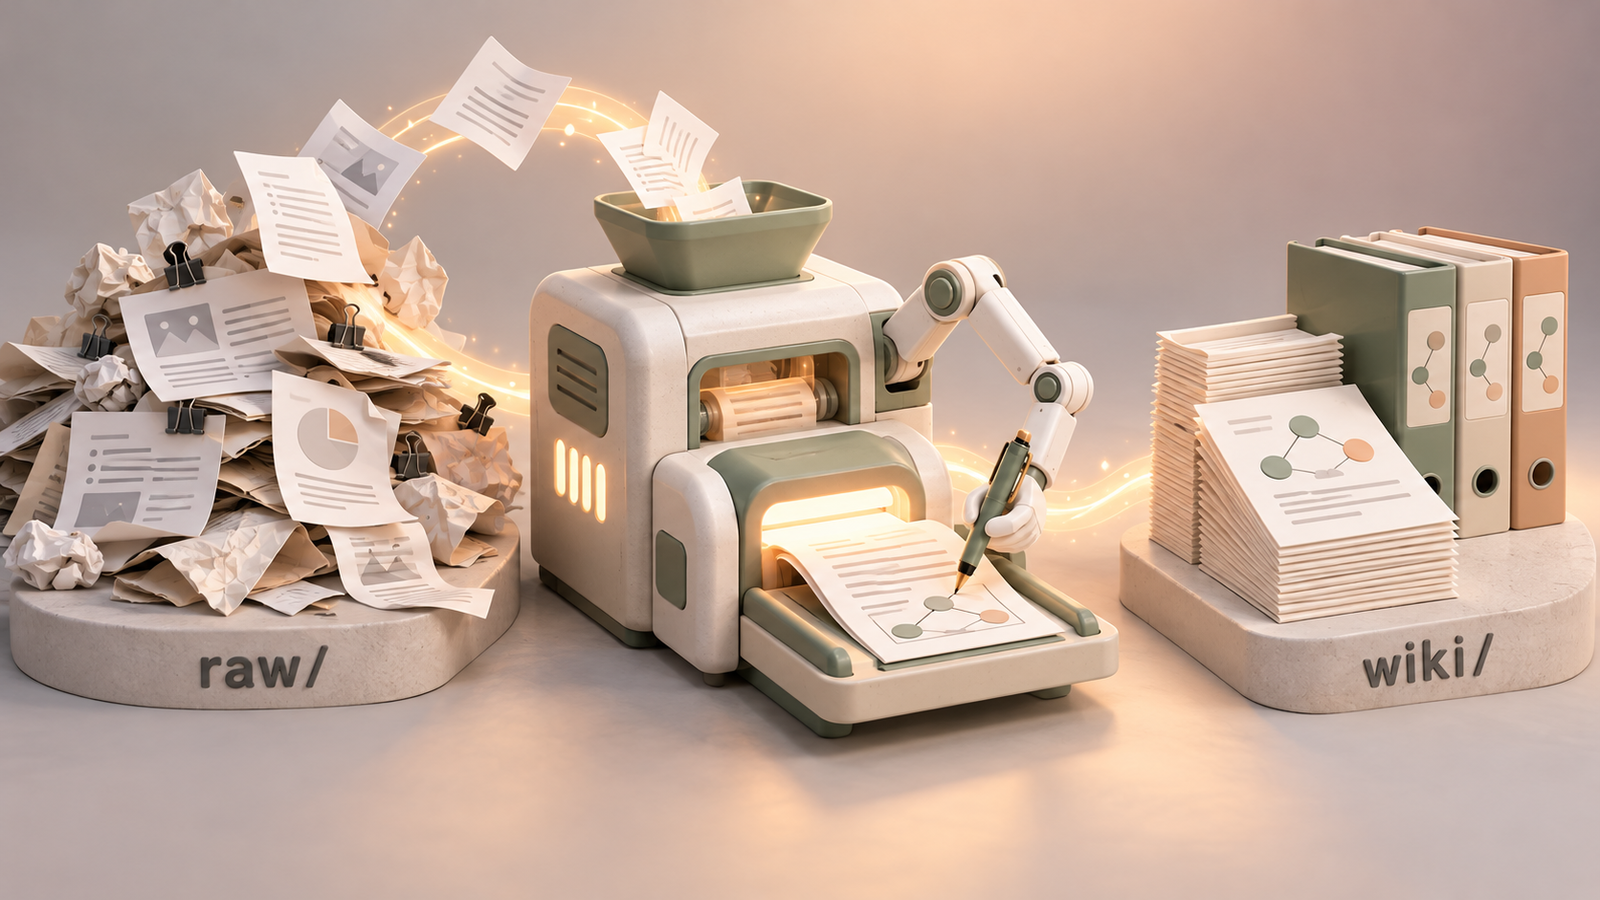
His system is split into three directories, raw, wiki, and output. The way a compiler pulls a binary out of source code, the LLM pulls structured knowledge out of raw material.
raw holds web articles, PDFs, datasets, and papers as they are, and once something goes in it’s neither edited nor deleted. It’s the foundation of every compilation, and if you lose the originals you can’t rebuild. wiki is where concept pages, entity profiles, summaries, and cross-references pile up. At the center sit index.md, which collects a one-line summary of every page, and log.md, an append-only chronicle of what came in and when.
The structure is public in a Gist, and a CLAUDE.md or AGENTS.md tells the LLM the wiki’s layout and the order of work. Using this schema means deciding how to structure your own domain.
If the wiki were a set of documents made once and left alone, it would’ve stayed a static archive. What makes this system different is that three operations repeat and the wiki keeps changing.
- Ingest: Put a new source in
rawand the LLM reads it, summarizes it, and updates the related pages. One source can touch 10 to 15 pages. He uses Obsidian Web Clipper to turn web articles into markdown, and PDFs can go through a converter like Docling or Marker. - Query: Ask the wiki a question and the LLM finds the relevant pages from
index.md, reads them, cross-references them, and synthesizes an answer. Answers, slides, and charts pile up inoutput, and results worth keeping go back intowiki. - Lint: The LLM sweeps the whole wiki for contradictions between pages, missing cross-references, stale information, and candidates for new articles. Code has linters, and so does knowledge.
Ingest adds knowledge, query results feed back into the wiki, and lint fixes the errors. The more this cycle repeats, the more the wiki turns from a static archive into a living system.
#Compilation, not retrieval
For the past two years the standard answer to letting an LLM handle my knowledge was RAG. Put the documents in a vector DB, and when a question comes in, find similar chunks and put them in the context.
In basic RAG that relies on chunk similarity alone, all a vector DB sees is semantic similarity. It doesn’t know that chunk 4271 contradicts chunk 8903, or that newer research has already overturned 8903. Unless you preserve the relationships between documents separately, they disappear the moment you cut into chunks. There are variants that extract the relationships into a graph ahead of time, and those too have moved the relationships from query time to ingest time.
Compilation writes those relationships down ahead of time. Instead of searching when a question arrives, the LLM reads the existing wiki when a new source comes in and fixes the relationships. A contradiction is recorded as a contradiction, and superseded research as superseded.
| Aspect | Basic RAG | Compilation |
|---|---|---|
| What’s built ahead | Chunks and embeddings for retrieval | Summaries, cross-references, contradiction marks |
| Storage | Vector embeddings (chunks) | Markdown (pages) |
| Relationships | Semantic similarity | Explicit cross-references |
Karpathy’s wiki runs 100 articles and 400,000 words per topic, too big to put in the context whole but small enough to scan from index.md and read only the pages you need. He said he expected to need elaborate RAG, but the LLM managing the index file and the document summaries on its own turned out to be enough.
#The inflection point
The inflection point that made this structure possible isn’t the context window. Gemini 1.5 Pro already offered a million tokens in February 2024, and that alone never got as far as an LLM maintaining a wiki by itself.
Three prerequisites stacked up in order. Context windows widened until index.md and several pages could be read at once, and markdown became the LLM’s default format, read and written without conversion. On top of that, agents like Claude Code and Codex began to operate on files directly. Reading, then reading and writing, then reading, writing, and maintaining.
The third is what matters. Before agents, an LLM could read my documents but couldn’t edit several files and repeat the job, and maintaining the wiki was always a human’s job. Once the filesystem API opened, the wiki passed into the LLM’s hands.
Karpathy isn’t the only one who went this way. Shopify CEO Tobi Lütke released qmd, a local markdown search engine that combines full-text search, vector search, and LLM reranking. Where compilation sorts out the relationships between pieces of knowledge ahead of time, qmd takes the job of finding what you need in those markdown files. Tiago Forte, who wrote Building a Second Brain, redefined personal knowledge management in 2026 as personal context management. It meets this wiki in that both design which information to hand the AI, and when.
There are two limits. One is accuracy. Karpathy didn’t put numbers on how many contradictions lint catches and how many it misses, or on how a wrong summary spreads once it’s in the wiki, and I haven’t measured it yet either. The other is scale. As long as index.md and the pages you need fit in the context, compilation is enough, and past that line you need search like qmd again. Up to that line there’s no need for a vector DB or a custom API. For an LLM, a filesystem is enough.
#References
- Andrej Karpathy, LLM Knowledge Bases (X). The original post saying token usage is moving from code to knowledge.
- Karpathy, llm-wiki Gist. The public note laying out the structure that maintains the wiki with
CLAUDE.md,index.md, andlog.md. - Hacker News, LLM Wiki discussion. The community thread that rose to the top after the post went up.
- Tiago Forte, Introducing The AI Second Brain. Redefines personal knowledge management as personal context management.
- qmd by Tobi Lütke. A local markdown search engine that combines full-text search, vector search, and LLM reranking.